BOCOM International — Foundation Model Series (1): From Open Source to Frontier: Kimi K3 Technical Report Analysis
Summaries are public. PDF access requires an active membership; all members have the same access. Sign in
Key Views
- Benchmarks the weighted average US-dollar cost of completing standard intelligence test tasks.
- Evaluates real-world software development performance—solving multilingual, multi-tech-stack problems end to end—compute cost-effectiveness, and agents' capabilities for multi-step search, information screening, and deep research in complex open web environments.
- Assesses general intelligence and productivity conversion in economically valuable professional work, including agents' end-to-end execution of multi-step knowledge tasks with usable deliverables in white-collar settings.
- Examines Moonee's technical principles, notably "perfect load balancing."
Outlook
Table 18 shows eight evaluation scores and tool-use steps rising with each step-up in RL compute, validating reinforcement learning as a second scaling axis. Table 20 compares Moonshot AI's major past financing rounds.
Key exhibits
Exhibit 1

Exhibit 2

Exhibit 3

Exhibit 4

Exhibit 5

Exhibit 6

Exhibit 7
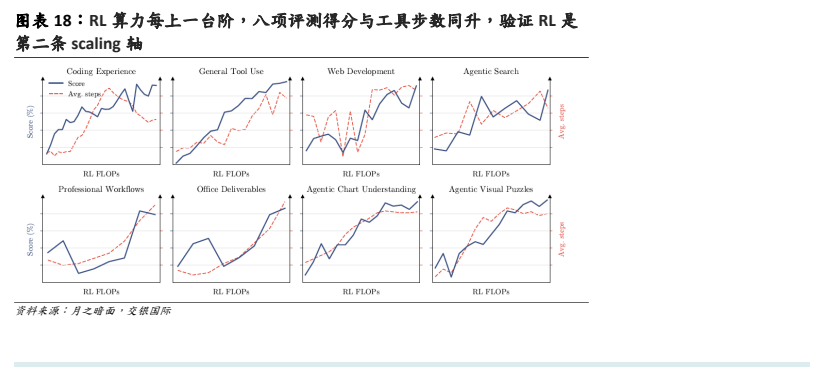
Exhibit 8
